Machine Learning Part 2: Data, Features and Embeddings
Learn the key machine learning data concepts: structured data, features, labels, preprocessing, validation, bias, variance, and embeddings.
Let's look at this more closely. This article continues Part 1, which you can read here.
We said that models can train on several kinds of data, including text, images, numbers, and videos. But those kinds of data can also be divided into categories.
What do you mean by categories?
There are several types of data:
- Structured data is organized into tables, rows, and columns. It can contain numbers and text. Examples include data in SQL databases such as PostgreSQL, SQL Server, and MariaDB, as well as Excel spreadsheets and CSV files.
- Unstructured data includes large amounts of text, images, and videos. It can be stored in NoSQL systems, object storage, or file systems. Examples mentioned here include MongoDB, Redis, and Neo4j. Data can also be represented in JSON.
- Semi-structured data combines some organization with a flexible structure. JSON and XML are common examples.
Does that mean we take this data and train the model on it?
Exactly. You will also hear the term dataset. It means the collection of data the model reads and learns from after the processing steps we discussed. A dataset does not have to be a single file.
Key terms in the data processing pipeline
- Sample: An individual example or a selected part of the available data. A sample can be chosen deliberately or randomly. In a table, each row can be a sample.
- Feature: An input attribute, often represented by a column such as
AgeorSalary. - Target: The value we want the model to predict. Some machine learning tasks do not have a target column, such as unsupervised learning. We will discuss that later.
- Input and Output: Input is what we give the ML Model. Output is what the model returns, such as a prediction of the target.
- Label: The actual value of the target. For example:
Age Salary Bought
20 5000 Yes
Features: Age, Salary
Target: Bought
Label: Yes
- Ground Truth: Highly accurate, verified information used as a reference when training, validating, or testing a model.
- Numerical Features: Features whose values are numbers.
- Categorical Features: Features whose values represent categories.
- Record: A row containing data. Depending on the context, you may also hear it called an observation, instance, or sample.
- Missing Values: Values that are absent from a record.
- Outliers: Values that are unusually far from what is normal or expected for the particular case.
- Noise: Random information, errors, or signals that do not represent the real relationship in the data.
- Duplicate Data: Repeated data. Before removing duplicates, we should understand whether the repetition carries useful information.
- Normalization: Scaling numerical values into a chosen range, such as 0 to 1 or -1 to 1, depending on the method.
- Standardization: Transforming numerical data so that it has a mean of 0 and a standard deviation of 1. This can help some machine learning algorithms train more effectively.
- Encoding: Converting non-numerical data into numerical representations a model can use. Examples include One-Hot Encoding, Label Encoding, and Ordinal Encoding.
- One-Hot Encoding: Creating separate binary columns for categories. The column for the present category gets
1, while the others get0. - Label Encoding: Assigning a number to each category. For example, three car brands might receive the numbers
1,2, and3. Depending on the model, those numbers may imply an order that the categories do not actually have. - Ordinal Encoding: Encoding categories that have a meaningful order or ranking.
- Train-Test Split: Dividing data into training and testing portions.
- Data Leakage: A model sees information during training that it should not have had. This can produce misleadingly strong results.
- Validation Set: A portion of the training data used to compare models or choose hyperparameters. After selection, we may retrain the chosen model on the combined training and validation data before the final test.
- Parameters: Values the algorithm learns from data during training, such as weights
Wand biasb. - Hyperparameters: Settings chosen outside the training process that influence how the algorithm learns.
- Cross-Validation: Repeatedly training and evaluating on different splits to get a better estimate of performance on unseen data.
- Feature Selection: Choosing the features that are useful and influential for the task.
- Feature Engineering: Creating new features by deriving or combining information from existing data.
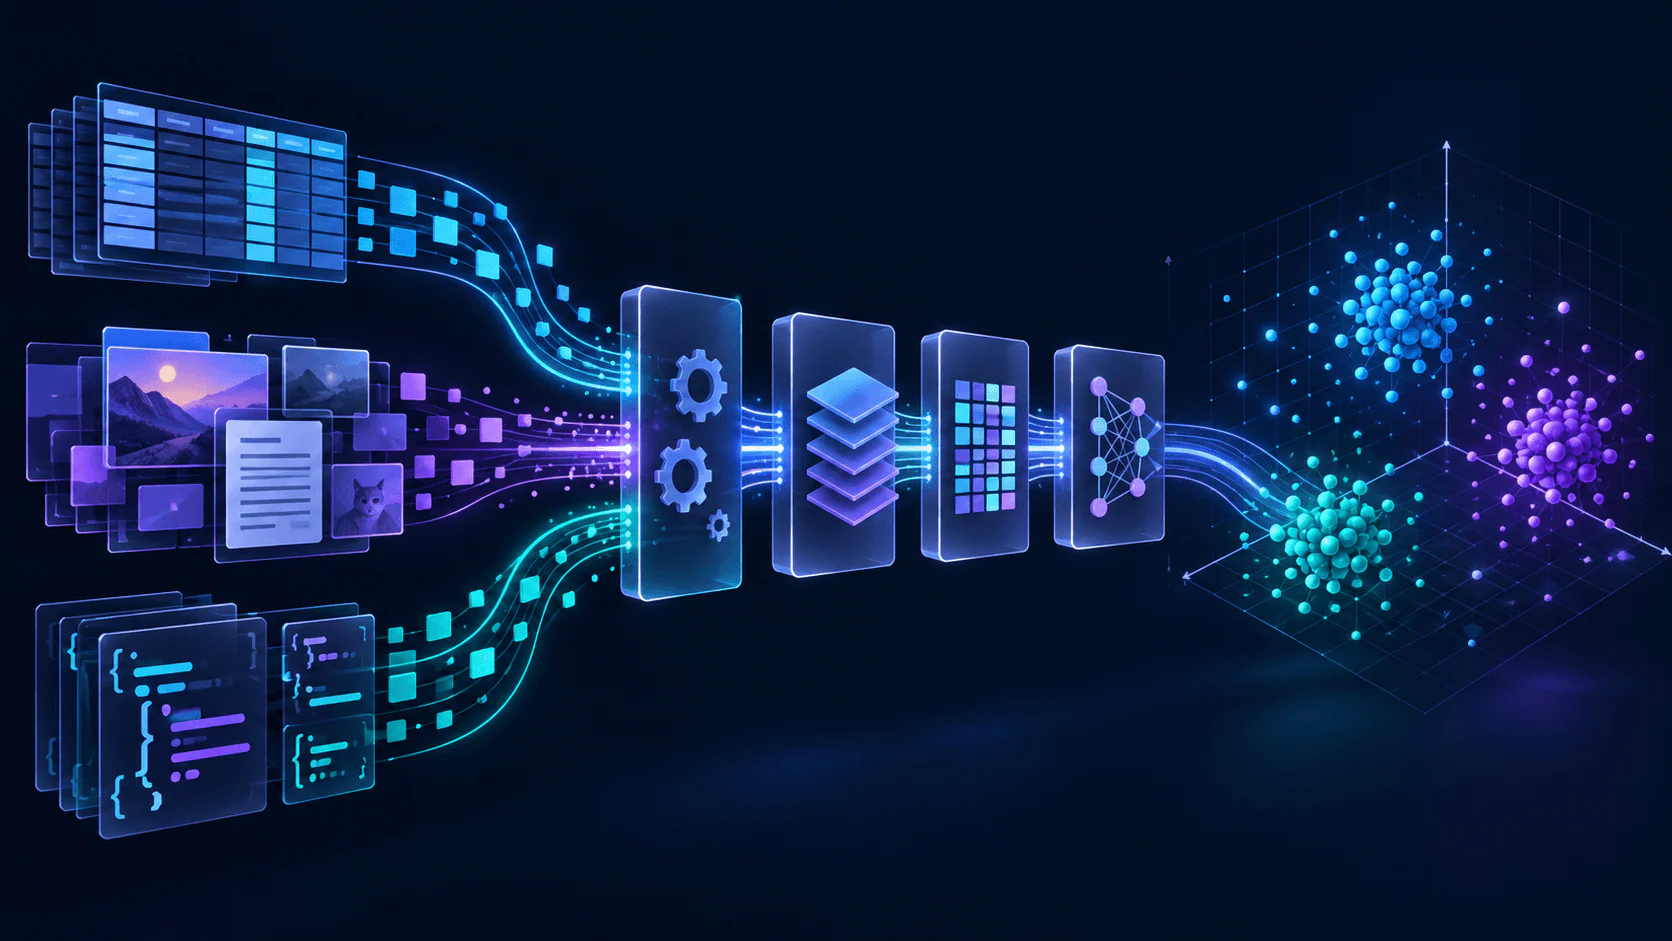
- Pipeline: The sequence of steps in a workflow, for example: CSV -> Cleaning -> Encoding -> Scaling -> Training -> Evaluation -> Prediction.
- Loss Function: A way to measure how wrong the model's predictions are during training. The model tries to reduce the loss over repeated training steps. This leads us to Gradient Descent. Metrics such as Accuracy are used to evaluate prediction performance.
- Gradient Descent: An optimization method used to reduce loss. We will return to it later.
- Underfitting: The opposite of Overfitting. The model has not learned the underlying relationship in the data well enough.
- Bias: In the bias-variance discussion, this describes how far the model's average prediction is from the true value. High bias is often associated with underfitting.
- Variance: How much a model's predictions change when it is trained on different data. High variance can mean the model has learned training details, including noise, too closely and may overfit.
- Generalization: The ability to perform well on new data the model did not see during training.
- Prediction: The outcome a model produces for a particular input.
- Inference: Using a trained model to produce an output. We will discuss how this appears in LLMs later.
Balancing Bias and Variance
We try to balance Bias and Variance so that both are as low as possible.
Imagine an archery target:
- Low Bias, low Variance: The arrows land close together near the center.
- High Bias, low Variance: The arrows land close together, but away from the center.
- Low Bias, high Variance: The arrows are spread out around the target, but their average is near the center.
- High Bias, high Variance: The arrows are spread out and away from the center.
Whatever kind of data we work with, it goes through a data preprocessing pipeline so it can be prepared for the task.
How do we process text, images, video, and audio?
Eventually, these inputs are represented numerically. A single number, such as 10, often cannot capture a useful meaning on its own. This is where vectors become useful.
Vectors? You mean mathematical vectors?
Exactly. A vector represents something using a collection of numbers.
I still do not understand.
Take the word “lion” as an example. We can represent it with a vector: a collection of numbers that captures characteristics or meaning mathematically. One common way to create such representations is through embeddings.
How does that help us?
It lets us compare related things. For example, vectors for “lion” and “cat” may appear closer together than vectors for unrelated words in a vector space.
Embeddings are a common type of vector representation used for this purpose.
Written by
Mohamed Alawakey
ML & AI Engineer documenting practical decisions from building RAG, LLM, machine-learning, and FastAPI systems.