Introduction to Machine Learning: Part 1
A beginner-friendly introduction to machine learning, covering data, models, training, testing, accuracy, overfitting, and when to use ML.
What is Machine Learning?
The term Machine Learning has two parts: “Machine” means the machine or device we have, and “Learning” is the process we make the machine go through so that it can learn. The term ultimately tells us that the machine learns.
That brings up a few good questions:
- Does the machine learn? Does it have a mind like ours so it can learn and understand?
- If it learns, what does it learn?
- How does the machine learn?
The machine does not have a mind. At the end of the day, it is an electronic device. It does not understand languages; it understands only 0s and 1s. So it does not inherently understand exactly what we give it.
Does that mean we have to give it 0s and 1s?
Of course not. We prepare the data so the machine can work with it; we do not manually give it 0s and 1s.
What is data?
This leads us to the question of what the machine actually learns.
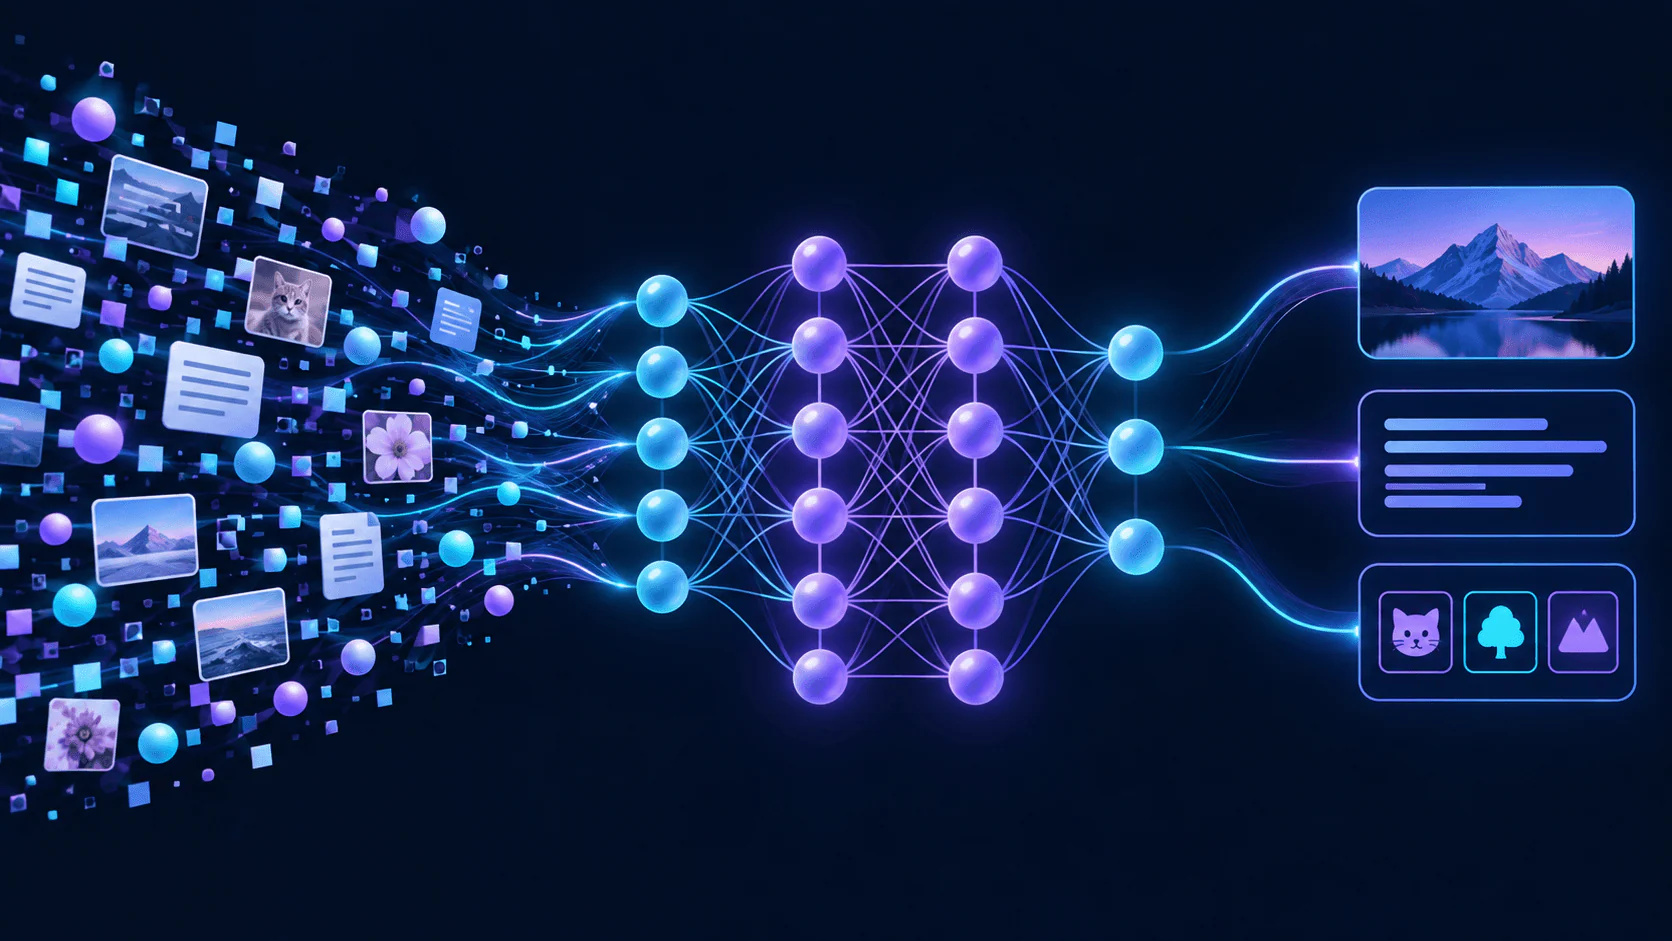
Data is what we rely on to make the machine learn. It is the source of information that the Machine Learning Model learns from.
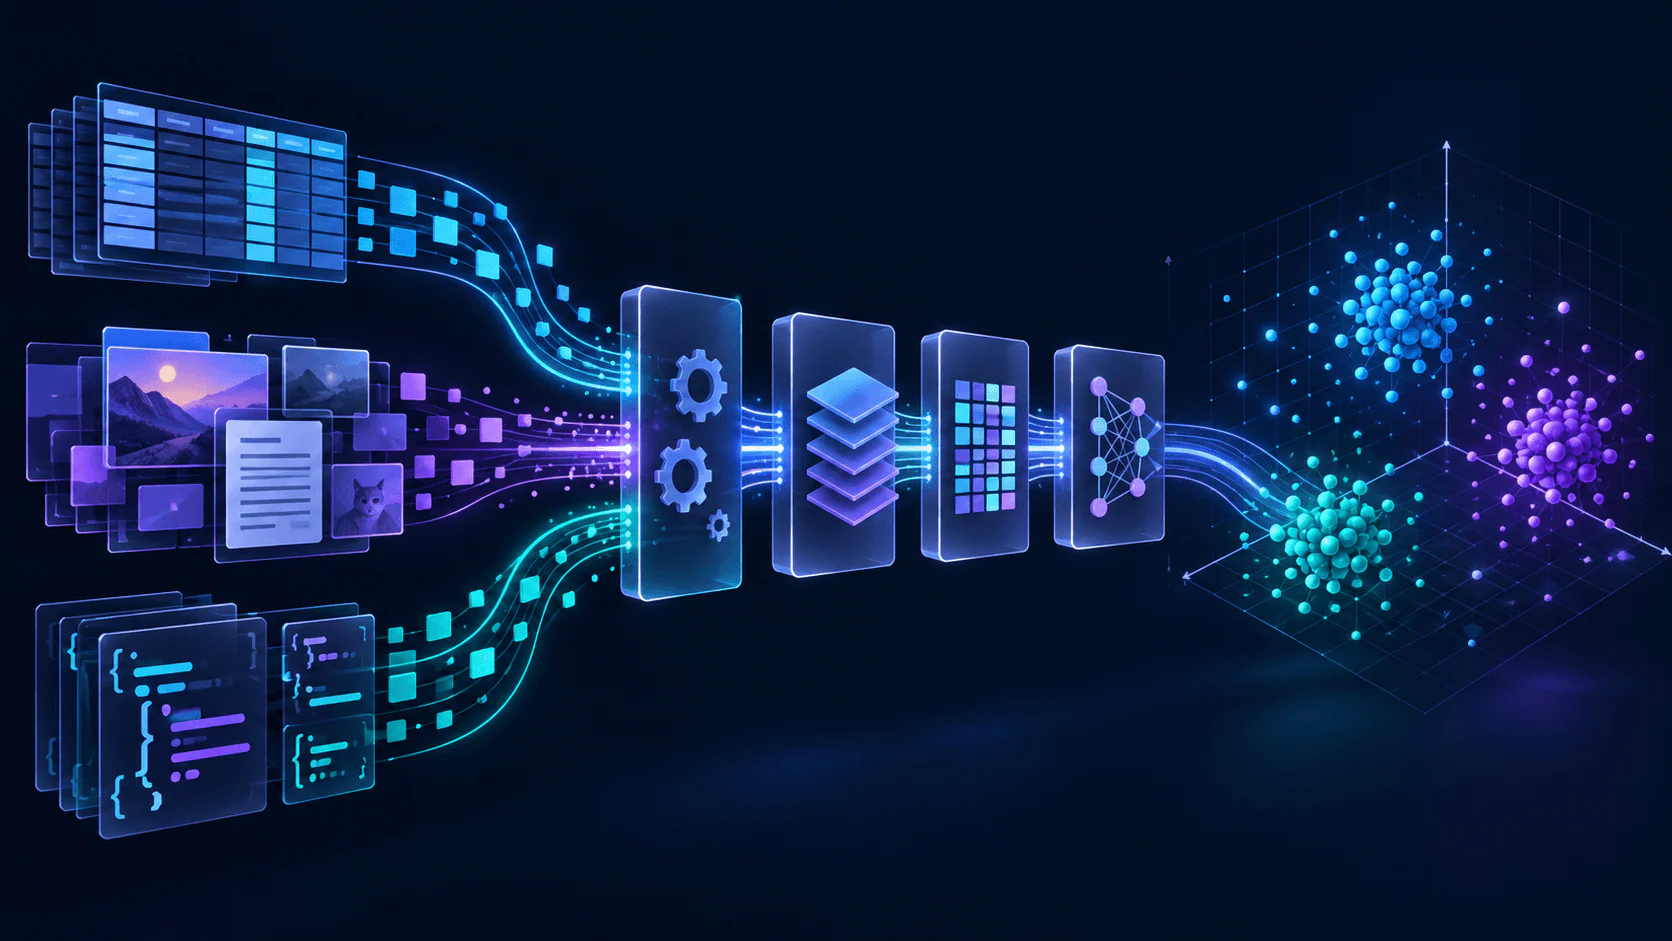
But we just said the machine only understands 0s and 1s. Does that mean we have to feed it data as 0s and 1s? Actually, no. This is where data processing comes in.
What is data processing?
Data processing means preparing data in a form the Machine Learning Model can use, whether that data is text, numbers, images, or videos. Processing can take a long time and is often one of the most time consuming parts of data science, Machine Learning, and AI in general, because they all depend on data.
The process starts with data understanding -> data analysis -> data cleaning -> data processing for modeling.
What is a Model?
The Model is what we train to learn from the data we have through mathematical equations, so it can understand the data.
Keep in mind that “learn” does not mean learning in the human sense. It means finding relationships within the data itself.
What do mathematical equations have to do with Machine Learning?
Machine Learning is built on Math, Statistics, Probability, Linear Algebra, Optimization, and Computer Science.
But why do we need them?
We use Math to find an equation that represents a pattern in our data. We say the model has been trained when we find an equation that achieves a good result. We cannot expect an equation to fit every single data point. So the “Learning” we have been talking about is not literal human learning; we use Math to help us find patterns in the data.
What do Statistics and Probability have to do with all this?
We build Models that learn from the data we have to help us predict something unknown. Those predictions are based on the data available to us. That is why we need Statistics and Probability. We also use them to understand and describe data, measure uncertainty, build some Models, evaluate results, test hypotheses, and calculate prediction probabilities.
What does it mean for a trained model to achieve a good result?
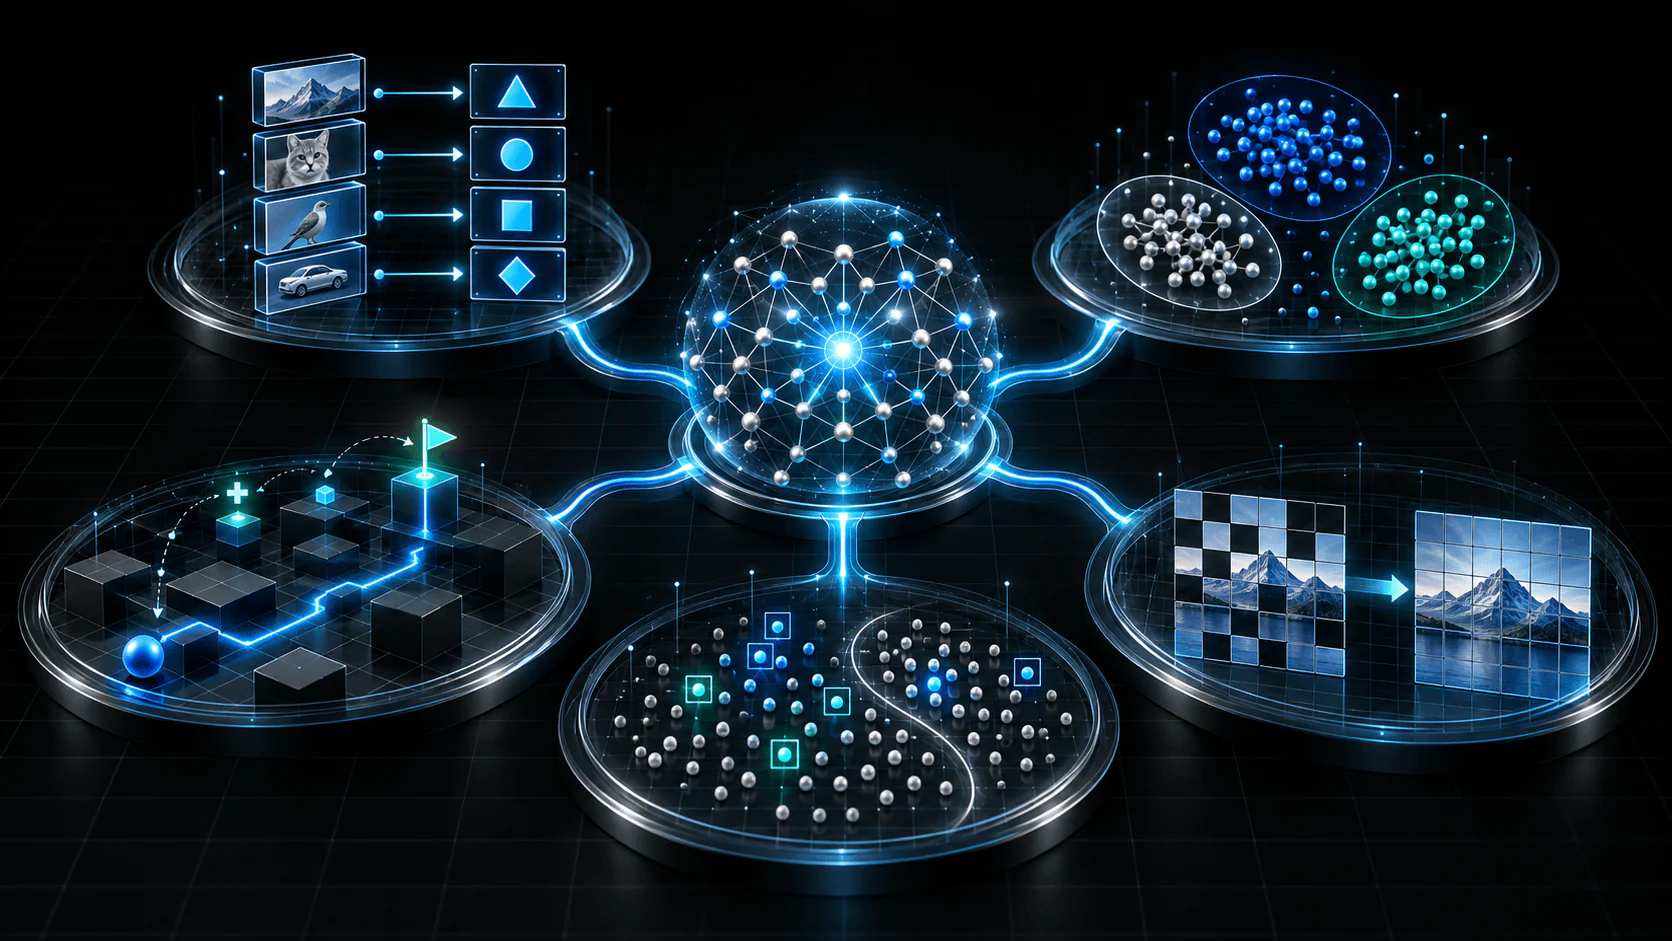
We said that a Machine Learning Model learns. We do not generally want it to memorize all the data, except perhaps when a pattern is extremely clear throughout the data. If it memorizes the data, we call that Overfitting. A model that has memorized almost all its training examples may make very few mistakes on those examples. But when we give it something new that it has not seen, it may answer incorrectly. In other words, the model can be very good on the training data and very poor on the testing data.
I still do not get it!
Imagine we have some data and have trained a model. Now we need to test it to see whether its answers are right or wrong. This is called testing. We give the model values and ask it to predict an outcome. Sometimes it gets the answer wrong, which is normal. The important question is: how many answers does it get wrong compared with how many it gets right?
That brings us to Accuracy. It tells us how many predictions the model gets right out of all its predictions. Suppose we have 100 data points, train the model on 80, and test it on the remaining 20. If, across 100 predictions, it gets 90 right and 10 wrong, its Accuracy is 90%. In other words, it answers 90% of those questions correctly.
Why do we need Machine Learning?
Machine Learning solves a big problem for us. Sometimes we need to predict or analyze data coming from users so we can understand them better. Writing rules for every possible case could require a huge number of if conditions. Instead, we can train a Machine Learning Model on similar data. It can then handle incoming cases and save us the time of writing rules for all of them.
Is that all?
No. Imagine a system that monitors roads. How could we make it analyze images, detect or predict accidents, and automatically alert the relevant authorities with the location when an accident happens? This is a situation where we can train a Machine Learning Model on videos and images of roads with accidents, without accidents, and with warning signs of accidents. That helps the model monitor what is happening. Rule based programming is less useful for these kinds of image and video cases, and for many other cases that are difficult to handle with hand written rules.
When should we use Machine Learning or rule based programming?
The simple answer is that we use rule based programming when the number of conditions and decisions is small and manageable. We use Machine Learning for the kinds of cases described above.
Why split the data into training and testing sets?
In the Accuracy example, we trained the model on 80 of the 100 data points and tested it on the other 20. Why split the data?
We split the data into Training Data and Testing Data so we can check whether the Model has learned to generalize or has simply memorized the training examples. We use the test data for evaluation and to see whether Accuracy is good enough or whether we still need Optimization. Keep in mind that Accuracy is not always the best metric. There are other Metrics, including Precision, Recall, and F1 Score. Accuracy is the number of correct predictions divided by the total number of predictions, and it is most useful when the classes are balanced.
Is that everything there is to Machine Learning?
Of course not. Machine Learning is a whole field. It is not just about getting some data, cleaning and preparing it, training a model, testing it, and deciding whether to use it. There is much more to it, including the Algorithms we use for training.
What are Algorithms?
An Algorithm is the training method that helps the model find mathematical parameters that reduce the Loss and achieve better performance on new data, so we can make better predictions.
In short: it is the mathematical method the model uses to learn from data.
Written by
Mohamed Alawakey
ML & AI Engineer documenting practical decisions from building RAG, LLM, machine-learning, and FastAPI systems.